AI News8 min readBy JH Akash
Qwen4-Max Preview: 14 Days Live, 1M Context, No Price
Alibaba opened Qwen4-Max Preview on Nov 11 and retires it on Nov 25. It has a 1M-token context and a 393,216-token output ceiling, but no benchmarks, no model card and no per-token price.
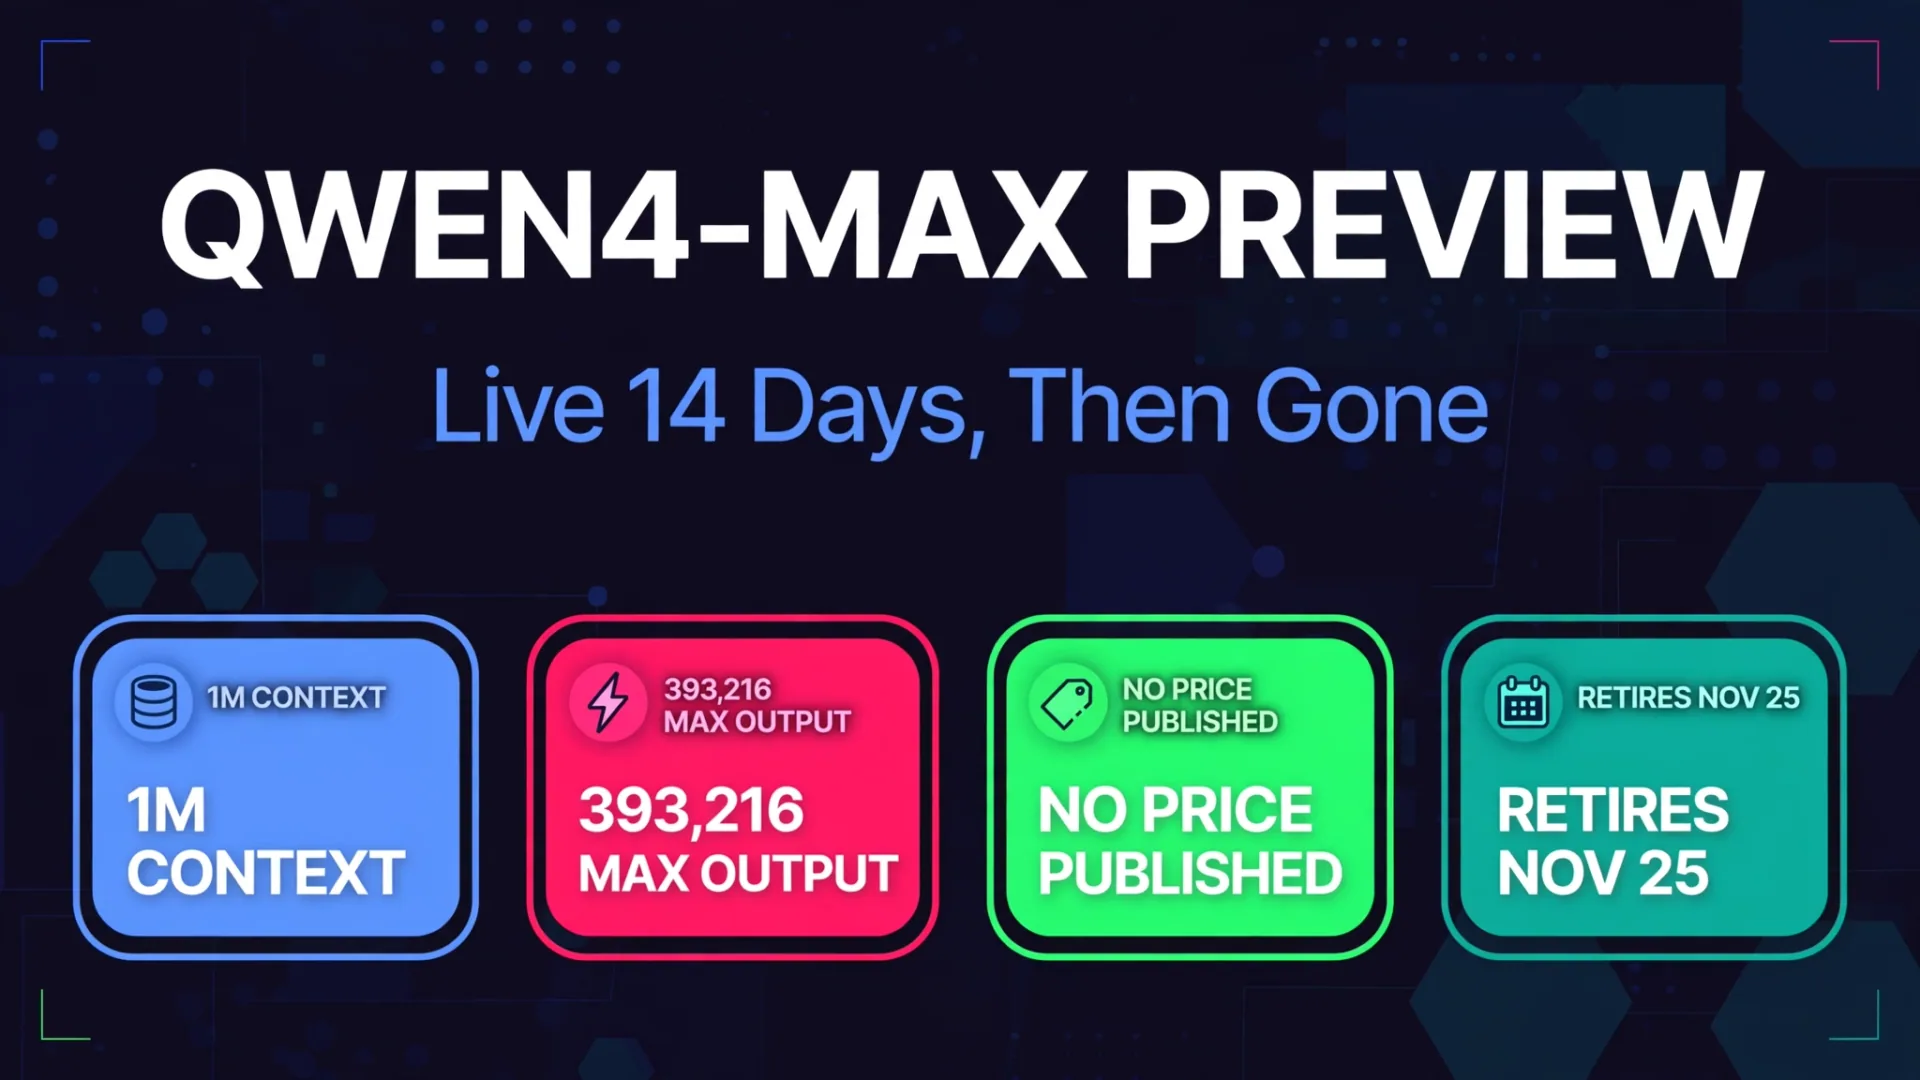
On November 11, 2026, Alibaba opened Qwen4-Max Preview, the first model of its Qwen4 generation. It comes with a sentence you almost never see on a flagship launch: the preview runs until November 25, no changes will be made during this period, and the model will be retired after the preview ends.
Fourteen days. Then gone. And Alibaba published no benchmark scores, no model card, no parameter count, no weights and no per-token price with it. Here is what the model actually is, what the early tests show, and whether it is worth your two weeks.
What Qwen4-Max Preview is
Qwen4-Max Preview is the early access version of Qwen4, Alibaba's next flagship generation, first shown at its Apsara conference in September 2026. It is the only Qwen4 model anyone can call today. The rest of the family, Qwen4-Plus, Qwen4-Flash and a 27B model meant for local deployment, has no announced date.
| Spec | Qwen4-Max Preview |
|---|---|
| Model ID | qwen4-max-preview (alias qwen4.0-max-preview) |
| Status | Preview, November 11 to November 25, 2026 (Beijing time) |
| Context window | 1,000,000 tokens |
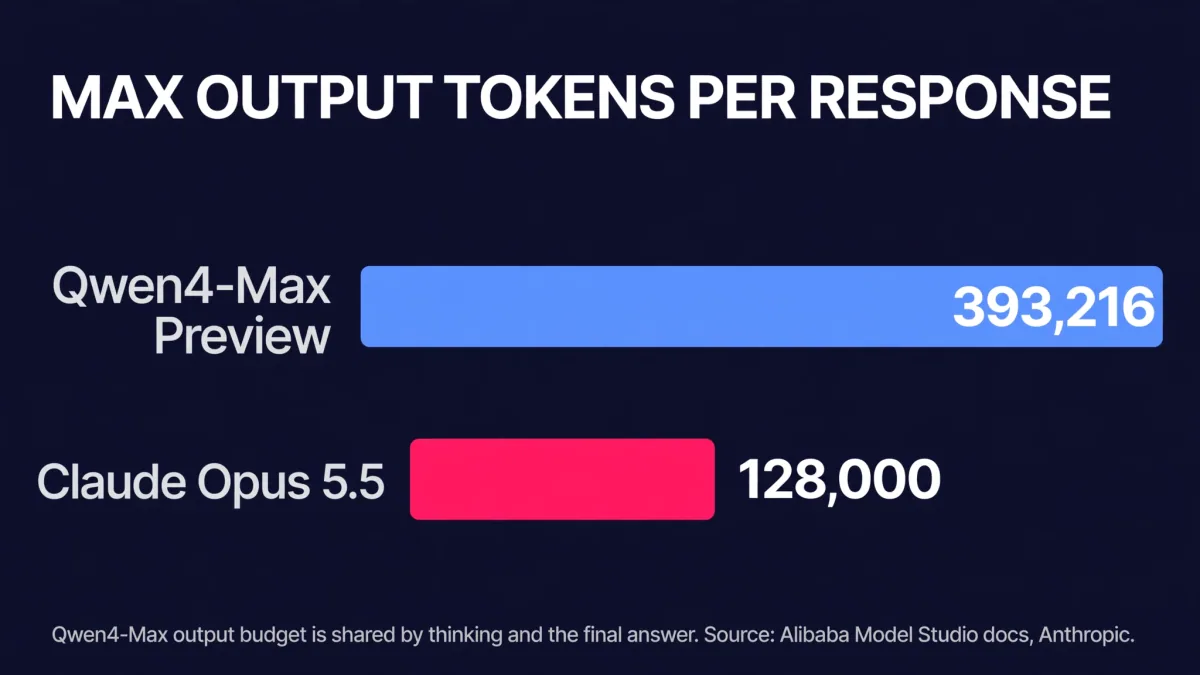
| Maximum output | 393,216 tokens, shared by thinking and the final answer |
| Input | Text, images and video |
| Thinking | On by default, reasoning_effort low, medium or xhigh (default xhigh) |
| Access | Token Plan subscription only, Singapore endpoint |
| Pay-as-you-go | Not supported, an ordinary Model Studio key does not open this model |
| Benchmarks | None published, vendor-reported or independent |
| Parameter count | Not published |
| Weights and license | Not published |
| Per-token price | Not published |
The 1M-token context is not new for the family. The previous flagship, Qwen3.8-Max, launched on August 3, 2026 with a million-token context of its own. What is new is the output ceiling: 393,216 tokens in a single response, with reasoning and the final answer sharing that budget. That is roughly three times the standard 128,000-token output ceiling of Claude Opus 5.5.
The quick verdict
Qwen4-Max Preview is a two-week test drive, not a model you can build on. The 1M context and the huge output ceiling are real and documented, and the first hands-on tests are fast. But with no benchmarks, no price per token and a hard retirement date, nothing you measure or build on this exact model survives November 25. Try it if you are curious or if you ship on Alibaba's stack. Do not migrate production work to it.
| Question | Short answer |
|---|---|
| Is it fast? | Early tests say yes, much faster than Qwen3.8-Max on the same tasks |
| Is it good? | Unknown, no benchmark exists yet |
| Is it cheap? | No per-token price exists, only a Token Plan subscription |
| Can I build on it? | No, it retires on November 25, 2026 |
| Is it open weight? | No weights published |
Qwen4-Max Preview vs Claude Opus 5.5 vs Qwen3.8-Max
This is the honest comparison: the numbers that exist, and the blanks where they do not.
| Qwen4-Max Preview | Claude Opus 5.5 | Qwen3.8-Max | |
|---|---|---|---|
| Context window | 1,000,000 tokens | 1,000,000 tokens | 1,000,000 tokens |
| Max output per response | 393,216 tokens | 128,000 tokens (300,000 on Batches API) | Not published |
| Input types | Text, image, video | Text, image | Text, image |
| Artificial Analysis Intelligence Index | No score published | 59, ranked 5th of 74 | 34 |
| Price per 1M tokens | Not published, Token Plan only | $4 input, $20 output | Not covered here |
| Availability | Nov 11-25, 2026, then retired | Active, retirement not before Sep 22, 2027 | Active |
The context window is a genuine three-way tie at 1M tokens. The output ceiling is where Qwen4-Max Preview stands out, and the availability window is where it falls apart: 14 days against more than 300 days of guaranteed availability for Opus 5.5.
Pricing: a subscription, not a rate card
Alibaba has published no per-token price for Qwen4-Max Preview. The only way in is the Token Plan, a monthly subscription for coding and agent tools, and usage draws down monthly Credits. Independent coverage of the pricing page lists Individual plans at $6 (Lite), $10 (Essential), $18 (Standard) and $43 (Pro) per month, with a $3 per month launch offer for new users. Alibaba publishes no credits-per-token rate for this model, so there is no way to calculate a cost per task until you burn Credits and watch.
| Plan | Price per month |
|---|---|
| Launch offer for new users | $3 |
| Lite | $6 |
| Essential | $10 |
| Standard | $18 |
| Pro | $43 |
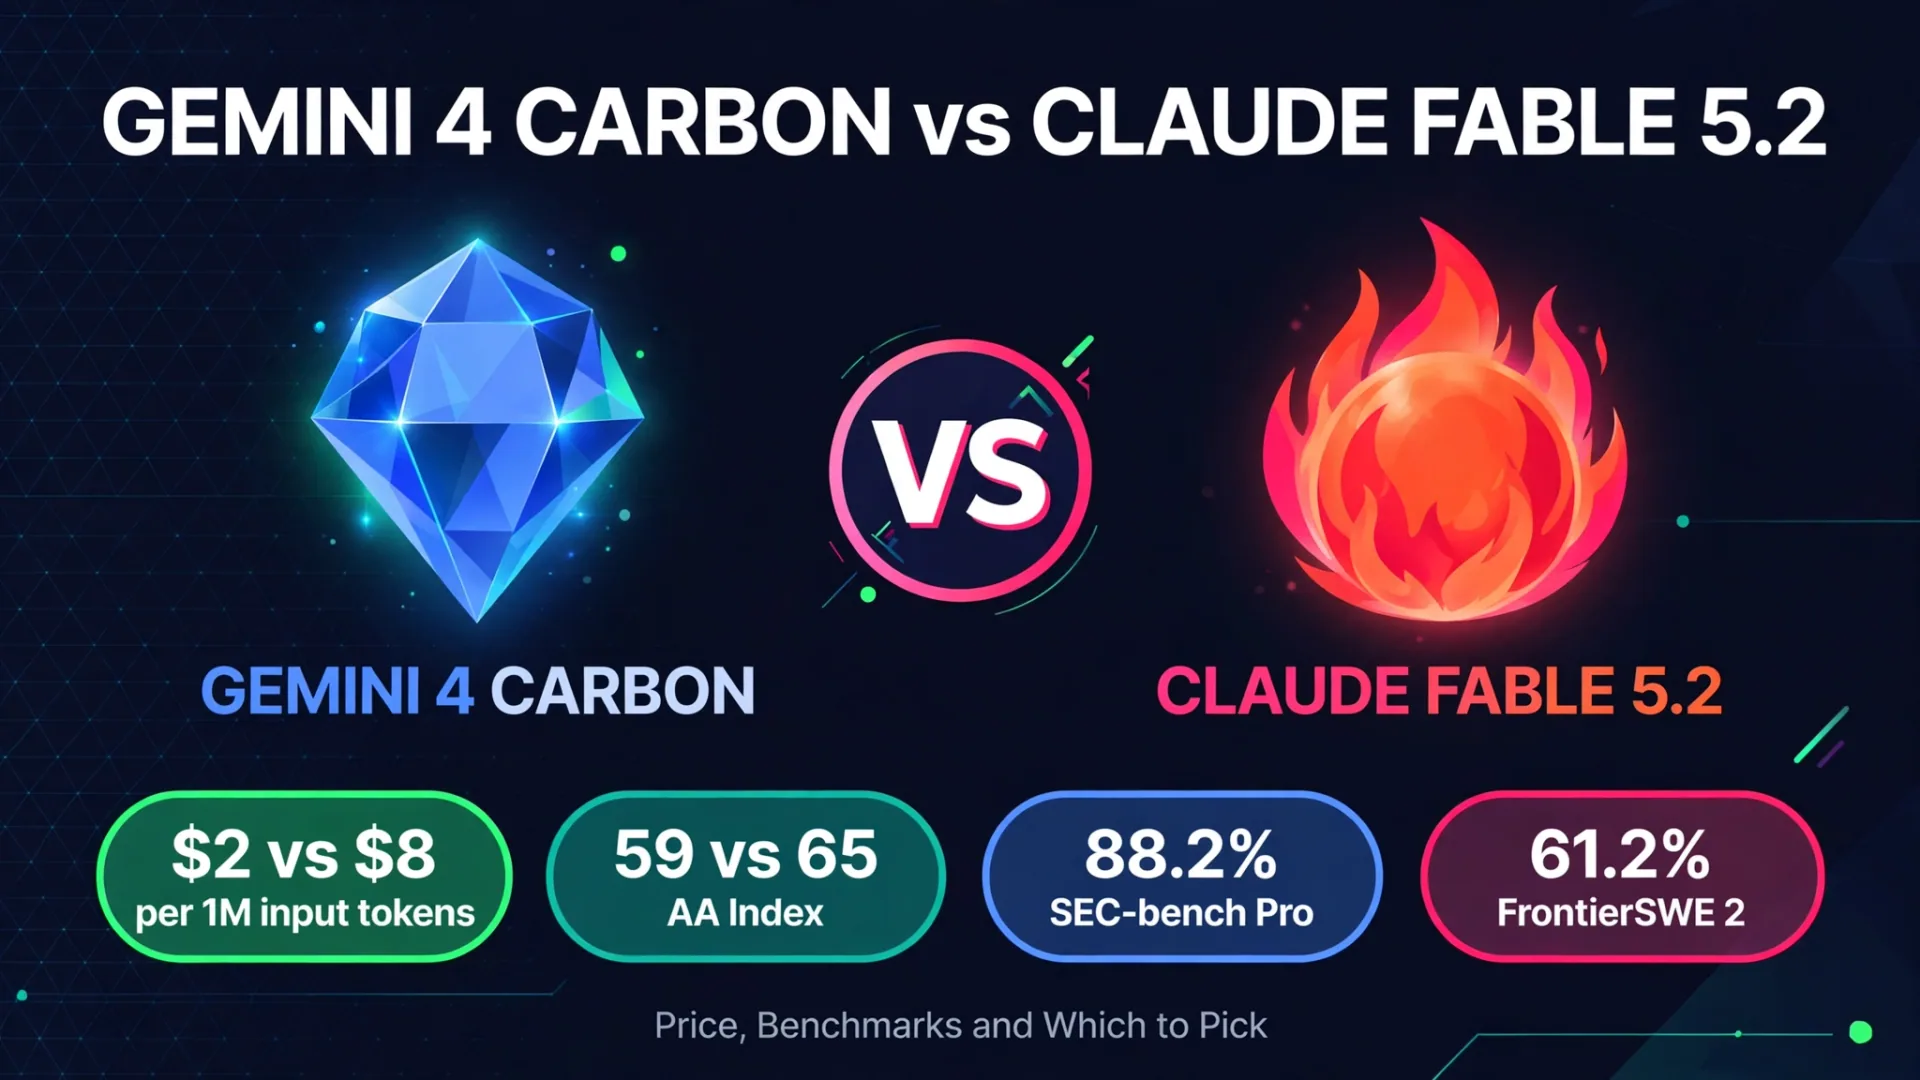
Compare that with the rate cards you can actually plan around: Claude Opus 5.5 at $4 input and $20 output per 1M tokens, and Gemini 4 Carbon vs Claude Fable 5.2: $2 vs $8 for the current price war at the top end. A subscription with no published per-token rate is the opposite of transparent pricing, and it is the weakest part of this launch.
Benchmarks: there are none
Alibaba's launch post and model documentation contain no benchmark numbers at all. As of November 12, no independent lab had published a score either. Artificial Analysis has no page for Qwen4-Max Preview, and LMArena had no score. A chart showing Qwen4-Max at 53 on the Artificial Analysis index is circulating on social media, but Artificial Analysis lists no Qwen4 entry, so treat that number as unverified.
What exists instead is a handful of hands-on tests:
| Early test | Result |
|---|---|
| 20 coding tests, Qwen4-Max vs Qwen3.8-Max | Qwen4-Max passed 20 of 20 in about 2.5 minutes, Qwen3.8-Max took 17 minutes |
| T-Rex game build test | Finished faster than Claude Fable 5.2 and Gemini 4 Carbon, but the tester still rated Fable 5.2 best overall |
| Speed vs GPT-6.1 Terra | One Hacker News user found Qwen4-Max slightly slower |
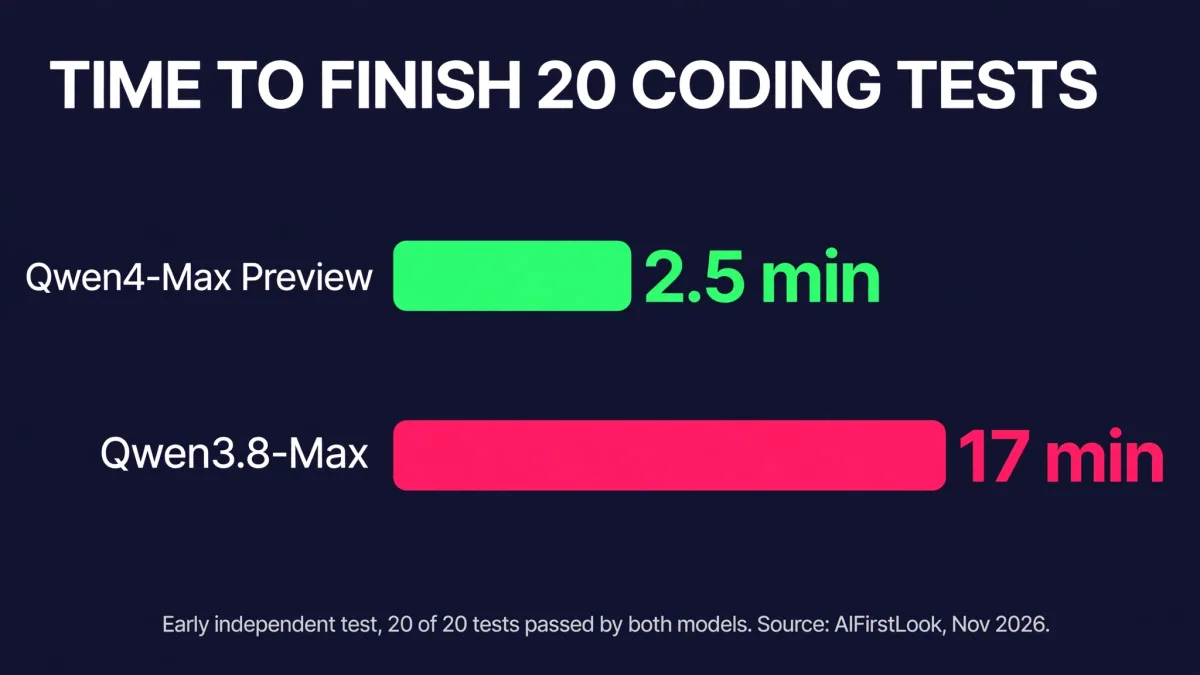
The 2.5-minute vs 17-minute result is the most striking early signal, about 6.8x faster than the previous flagship on the same 20 tests, with both models passing all 20. But it is one small test set from one tester, not a benchmark. Until a lab runs a real suite, every quality claim about Qwen4-Max is Alibaba's word or an anecdote.
For context on what real benchmark tables look like when they do exist, see Claude Fable 5.2: #1 at 65, 20% Cheaper, 30% Faster and Gemini 4 Hydrogen: 2.5x Faster, $1.50 Per 1M.
What is missing, and why it matters
The missing half of this launch is longer than the shipped half:
- No benchmarks. There is nothing to compare against Claude Fable 5.2, GPT-6 or Gemini 4 Carbon. Any page that ranks Qwen4-Max on quality today is guessing.
- No parameter count. Neither total nor active parameters are published, so memory and speed cannot be estimated from the architecture.
- No per-token price. Cost per task cannot be calculated, only felt after Credits are spent.
- No weights. Nothing named Qwen4 exists in the Qwen organisation on Hugging Face, so there is nothing to self-host or fine-tune.
- No model card. No published safety, training or evaluation documentation.
- No full release date. The rest of the Qwen4 family has no announced date, and the Token Plan page names no replacement for the preview when it retires.
Alibaba freezes the model for the window and retires it afterward, so any benchmark, cost estimate or safety test of this exact model stays useful only until November 25. That is the real story of this launch: a flagship you can test for two weeks and then lose.
Which to pick
Try Qwen4-Max Preview if: you already use Alibaba's Token Plan, you want to test the 1M context and the 393,216-token output ceiling on long agentic jobs, or you are evaluating Qwen4 ahead of the full release. Treat it as a demo with a deadline.
Skip it and use Claude Opus 5.5 if: you need a documented model with a published price, real benchmark scores and a retirement commitment. Opus 5.5 scores 59 on the Artificial Analysis Intelligence Index, costs $4 input and $20 output per 1M tokens, and is guaranteed available until at least September 22, 2027.
Skip it and use Qwen3.8-Max if: you want the Qwen family on a normal API today. It is the previous flagship, it has open weights, and it is not disappearing in two weeks.
Wait for the full Qwen4 release if: you want benchmarks, weights or a per-token price before you commit. The preview answers none of those questions.
If your team is deciding which model to build an AI product on, that choice matters far more than any single launch. Our guide on how to build an AI agent covers how to pick a model, set up evals and ship an agent that keeps working after launch.
FAQ
When does Qwen4-Max Preview retire?
November 25, 2026 at 24:00 Beijing time, which is 11:00 a.m. ET on November 25. Alibaba's documentation says no changes will be made during the preview period and the model will be retired after it ends.
How much does Qwen4-Max Preview cost?
There is no per-token price. Access runs through Alibaba's Token Plan subscription, with Individual plans listed at $6, $10, $18 and $43 per month, and a $3 per month launch offer for new users. Usage draws down monthly Credits, and Alibaba publishes no credits-per-token rate for this model.
Does Qwen4-Max Preview have benchmarks?
No. Alibaba published no benchmark table with the preview, and no independent lab had published a score as of November 12, 2026. A circulating chart claiming 53 on the Artificial Analysis index is unverified, because Artificial Analysis lists no Qwen4 entry.
What is the context window of Qwen4-Max Preview?
1,000,000 tokens, the same as Claude Opus 5.5 and the previous flagship Qwen3.8-Max. The maximum output per response is 393,216 tokens, shared by the model's thinking and its final answer.
Is Qwen4-Max Preview open weight?
No. No weights, license or parameter count have been published, and nothing named Qwen4 exists in the Qwen organisation on Hugging Face. The rest of the Qwen4 family, including a 27B model meant for local deployment, has no announced date.
How do I access Qwen4-Max Preview?
Through Alibaba's Token Plan only, on the Singapore endpoint token-plan.ap-southeast-1.maas.aliyuncs.com. Pay-as-you-go is not supported, and an ordinary Model Studio key does not open this model. It is also available in the Qwen app.
The bottom line
Qwen4-Max Preview is Alibaba's most unusual flagship launch: a big model with a big context window and a huge output ceiling, shipped with no benchmarks, no price and a 14-day expiry date. The early speed signal is real and impressive, but speed on one small test set is not quality, and a model that retires on November 25 cannot be the foundation of anything you ship. Test it this week if you are curious. Build on it never.
- Qwen4-Max Preview
- Alibaba Qwen
- Qwen4
- AI benchmarks
- AI pricing