AI News4 min readBy JH Akash
GPT-6.2 Astra vs Fable 5.2: 7-5 Win Costs 7.2x More
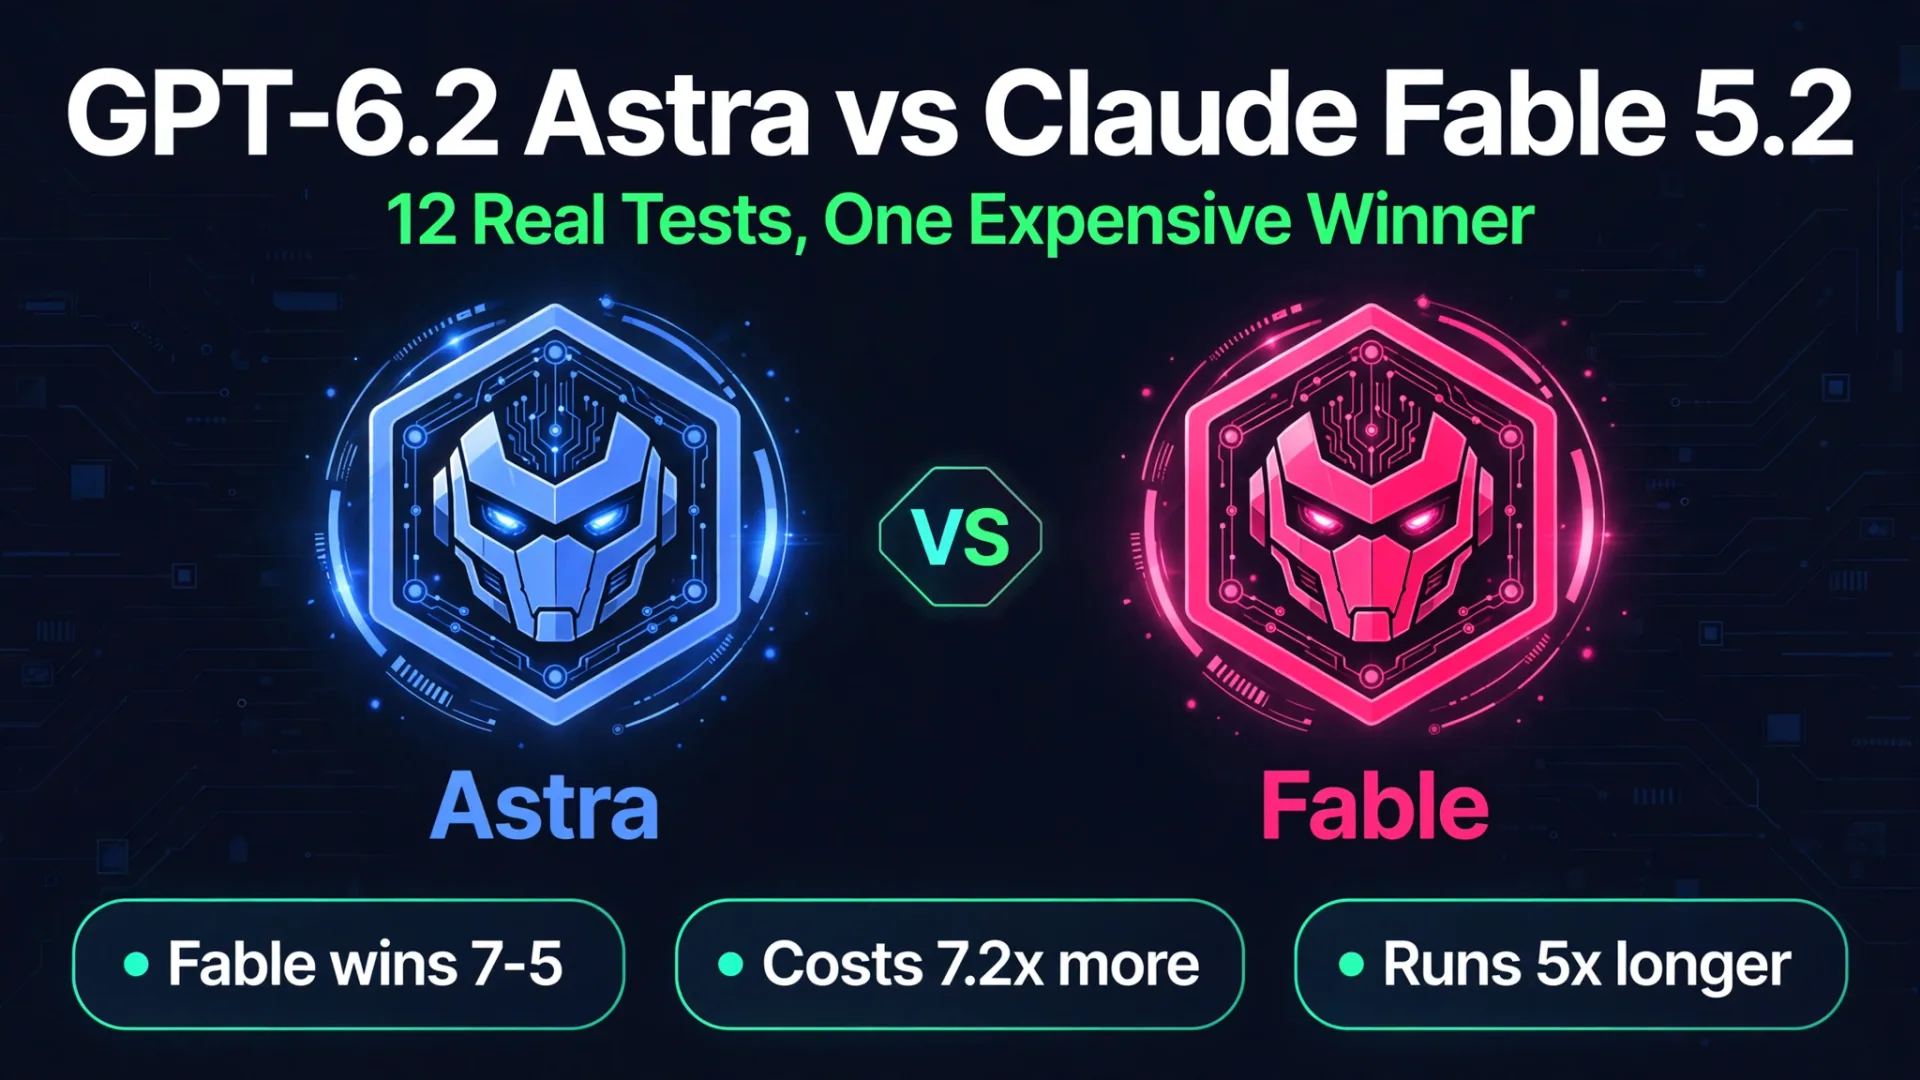
Fable 5.2 won 7-5 across 12 real tasks, but cost 7.2x more and ran 5x longer than GPT-6.2 Astra at the same $8/$40 price. Here are all 12 results.
The short answer
Claude Fable 5.2 won the head-to-head 7-5 across 12 real tasks, but it cost 7.2 times more in total and ran almost 5 times longer. Both models charge the same $8 input and $40 output per million tokens, so the gap is token efficiency, not price. GPT-6.2 Astra in Codex simply used far fewer tokens to finish the same work.
How the test worked
YouTuber Nate Herk ran both models on high effort with the exact same prompt for each task, on separate work trees so they could not interfere with each other. Fable 5.2 ran inside Claude Code, Astra 6.2 inside Codex. He tracked cost, input tokens, output tokens, and runtime for every run. The 12 tasks were web design, a slide deck, a Canva painting, an event recap video, a 3D virtual summit, an Instagram Reel, a YouTube edit, a learning guide, trip planning, an Instagram carousel, a financial model, and a browser game.
All 12 results
| # | Test | Winner | Fable 5.2 cost | Astra 6.2 cost |
|---|---|---|---|---|
| 1 | Web design | Astra 6.2 | $175 | $2.50 |
| 2 | Slide deck | Astra 6.2 | $9 | $2 |
| 3 | Canva painting | Astra 6.2 | $63 | $7.50 |
| 4 | Event recap video | Fable 5.2 | $15 | $4 |
| 5 | 3D virtual summit | Fable 5.2 | more expensive | similar time |
| 6 | Instagram Reel | Fable 5.2 | about 4x Astra | not shown |
| 7 | YouTube edit | Fable 5.2 | 5+ hours | $7 |
| 8 | Learning guide | Astra 6.2 | $17 | $3 |
| 9 | Trip planning | Fable 5.2 | $18.60 | $2.70 |
| 10 | Instagram carousel | Astra 6.2 | cheaper | cheaper |
| 11 | Financial model | Fable 5.2 | $15 | $2.50 |
| 12 | Browser game | Fable 5.2 | $19 | $3 |
Costs are the API-billing figures Nate showed in the video. Where a cost was not shown, the table says so.
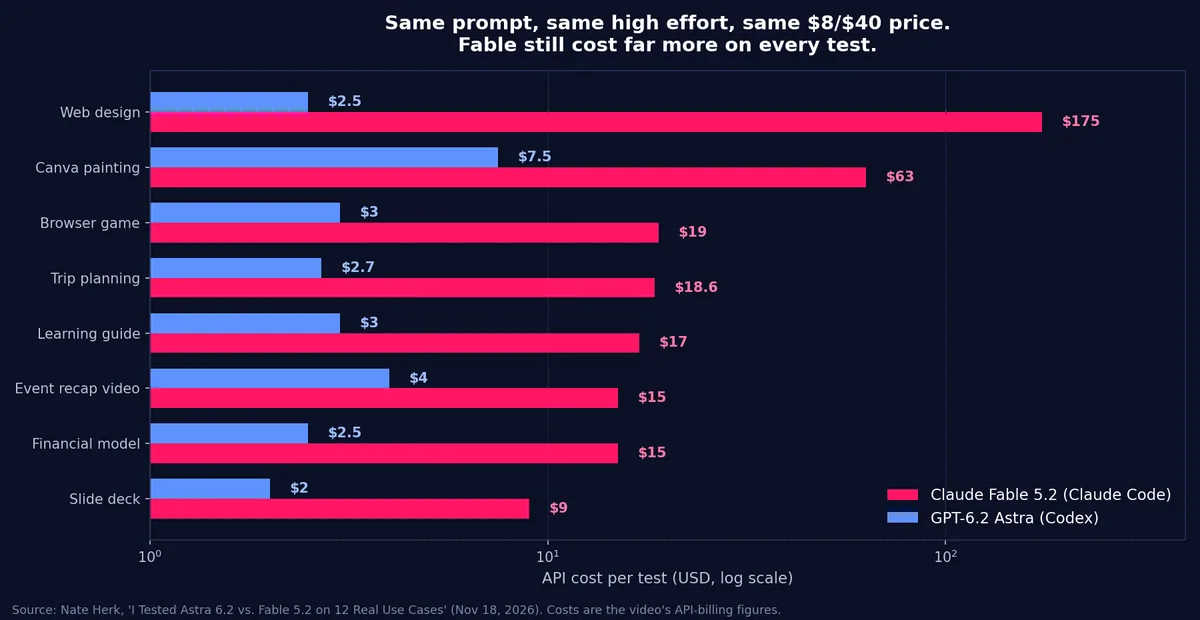
The tests that tell the story
Web design. Fable ran for 56 minutes and cost $175. Astra finished in 12 minutes for $2.50, and Nate picked Astra's cleaner site anyway.
Canva painting. Astra hit Canva's stroke limit, exported the work, and started painting over it again to get around the limit. Fable hit the same limit and stopped. Astra won, $7.50 to $63.
YouTube edit. Astra ignored the correct editing skill and used an old one, producing a cheap-looking edit for $7. Fable used the right skill and made the better video, but it took over 5 hours.
Trip planning. Astra's plan looked better, Fable's plan worked better, with real links and a fuller schedule. Nate's theme across the video: Astra wins on looks, Fable wins on logic.
Instagram carousel. Both models failed to follow the brand guidelines at all, even though the same workflow with Opus 5.5 normally nails them. A reminder that a skill must be tested on every model, not just one.
Same price, very different bills
| Per 1M tokens | Claude Fable 5.2 | GPT-6.2 Astra |
|---|---|---|
| Input | $8 | $8 |
| Output | $40 | $40 |
| Cached input | $0.20 | $0.40 |
Fable 5.2 launched on Nov 9, 2026, Astra 6.2 on Nov 17, 2026. Both cut their predecessors' prices by 20%. The per-token price is identical, so every dollar of the 7.2x gap comes from how many tokens each harness burns.
What the official benchmarks say
All numbers below are vendor-reported, so read them as each company's own claims, not independent tests.
| Benchmark | Fable 5.2 | Astra 6.2 |
|---|---|---|
| FrontierCode 2.0 (Anthropic) | 49.1% | 42.8% |
| FrontierSWE v2 (Anthropic) | 69.9% | 65.5% |
| Artificial Analysis Intelligence Index | 65 (1st) | 62 (2nd) |
| AA-3D (Artificial Analysis) | 1,271 Elo | 1,318 Elo (1st) |
| Agents' Last Exam (OpenAI) | behind by 5.5 pts | leads, at 5% of the cost |
One asterisk on OpenAI's Agents' Last Exam claim: its own footnote says the Fable 5.2 leaderboard results exclude nine tasks that used a fallback model. The vendor benchmarks and Nate's real-task test point the same way: Fable is stronger on raw quality, Astra is far cheaper per finished task.
Which one should you pick?
Pick Fable 5.2 when output quality matters most and the budget allows it: long agentic builds, financial models, and video edits where the result is the product.
Pick Astra 6.2 when you run the same kind of task often: web design, decks, guides, and anything where a 5x to 7x cost gap adds up fast.
For everyday coding, Anthropic itself still recommends Opus 5.5, which costs half as much as Fable 5.2 per token.
Nate's own takeaway: build a skill around the task, then let Astra run it. With the right skills and specific prompts, Astra gets close to Fable's output at a fraction of the cost.
If you want to build this kind of workflow yourself, start with our guide on how to build an AI agent. For the build-vs-buy decision behind it, see custom AI vs off-the-shelf AI, and for what these builds cost in practice, our AI development cost breakdown.
FAQ
Who won Astra 6.2 vs Fable 5.2?
Fable 5.2 won 7 of the 12 tests, Astra 6.2 won 5.
Why did Fable cost 7.2x more if both charge $8/$40?
Same per-token price, very different token use. Claude Code with Fable 5.2 burned far more input and output tokens per task than Codex with Astra 6.2.
Is GPT-6.2 Astra cheaper than Claude Fable 5.2?
Per token, no, they cost exactly the same. Per finished task, yes, Astra was cheaper on all 12 tests in Nate Herk's run.
Which model is better for coding agents?
For raw quality on hard, long tasks, Fable 5.2. For cost and speed on repeated work, Astra 6.2. Anthropic recommends Opus 5.5 for most everyday coding.
Source: Nate Herk, "I Tested Astra 6.2 vs. Fable 5.2 on 12 Real Use Cases" (Nov 18, 2026). Watch it here: https://www.youtube.com/watch?v=e5b4lgf2jXE
- GPT-6.2 Astra
- Claude Fable 5.2
- OpenAI
- Anthropic
- AI models
- Codex
- Claude Code