KI5 Min. LesezeitVon JH Akash
GPT-6.1 Sol vs Claude Sonnet 5.5: Real-World Tests Expose What Benchmarks Hide
Chase AI tested GPT-6.1 Sol vs Claude Sonnet 5.5 on 4 real build tasks. Sonnet won on quality, Sol costs $0.72 vs $7.60 per task. Full breakdown.
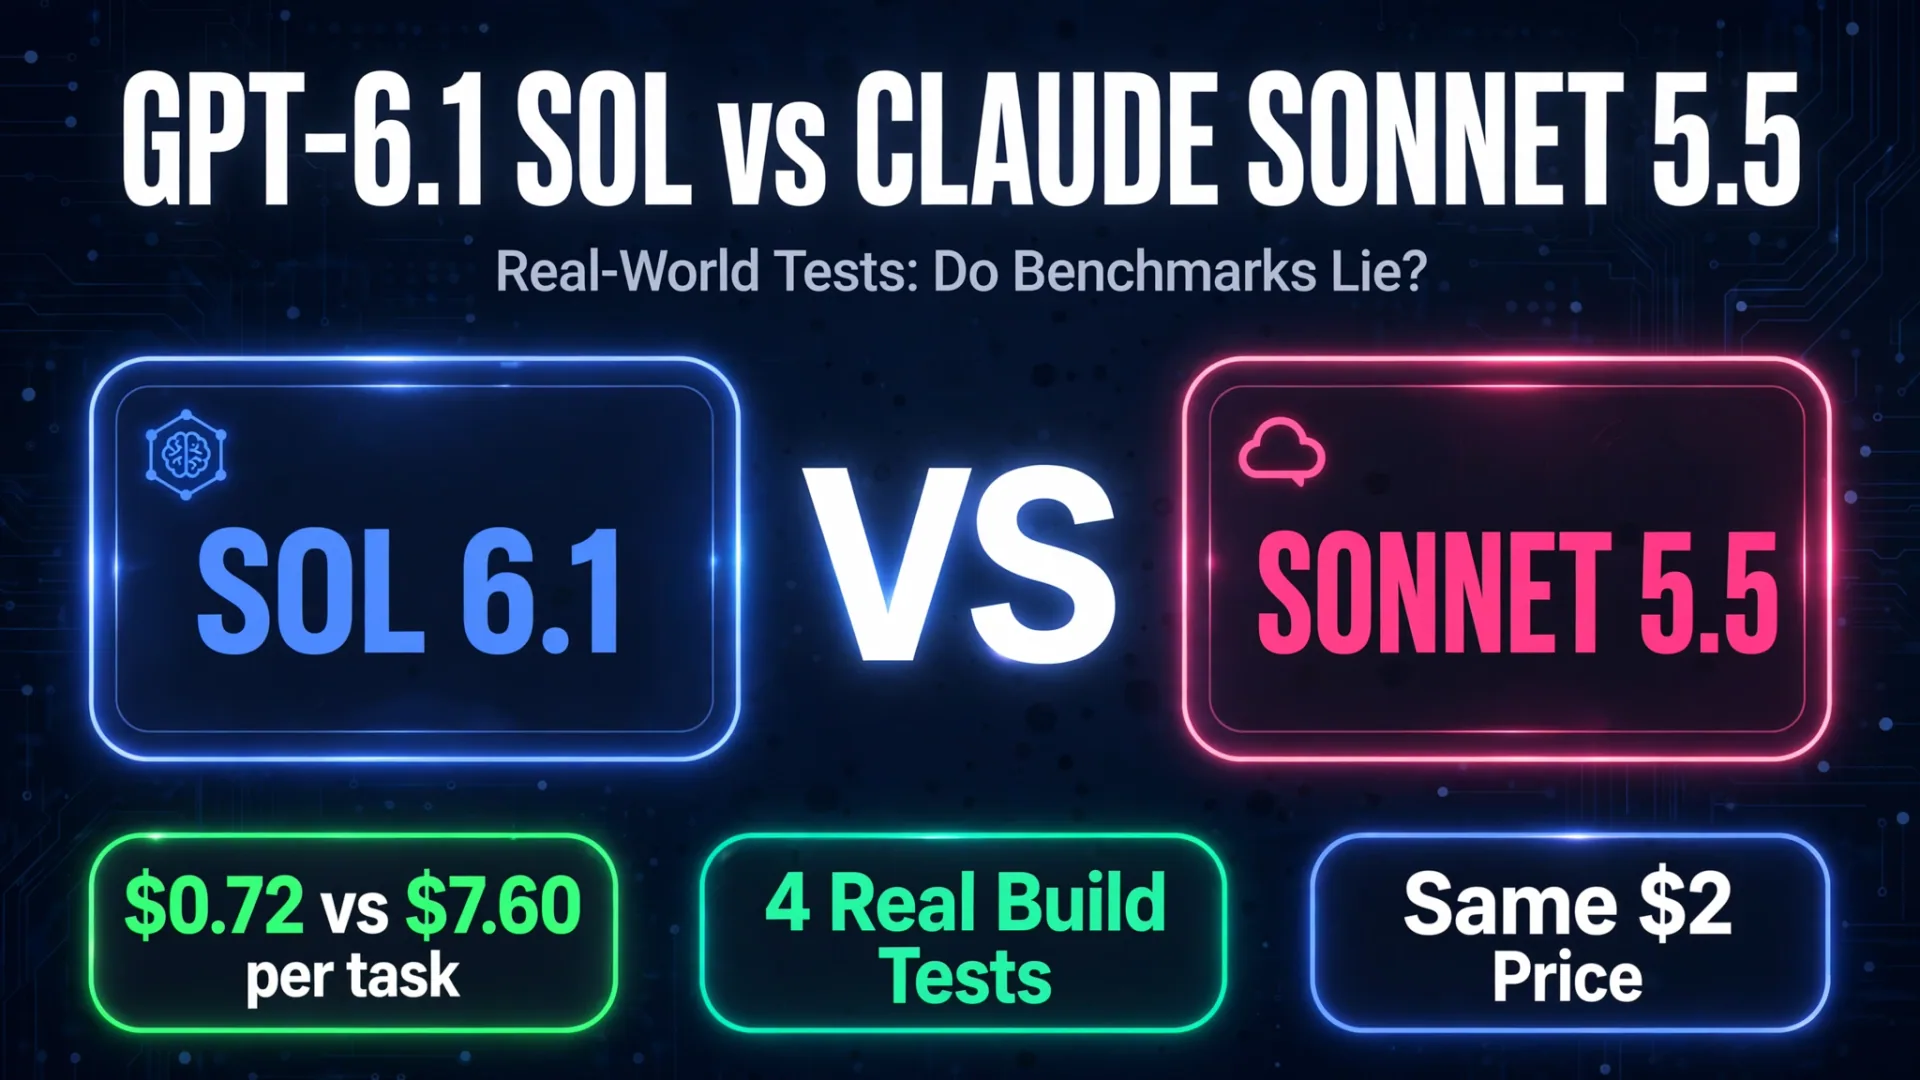
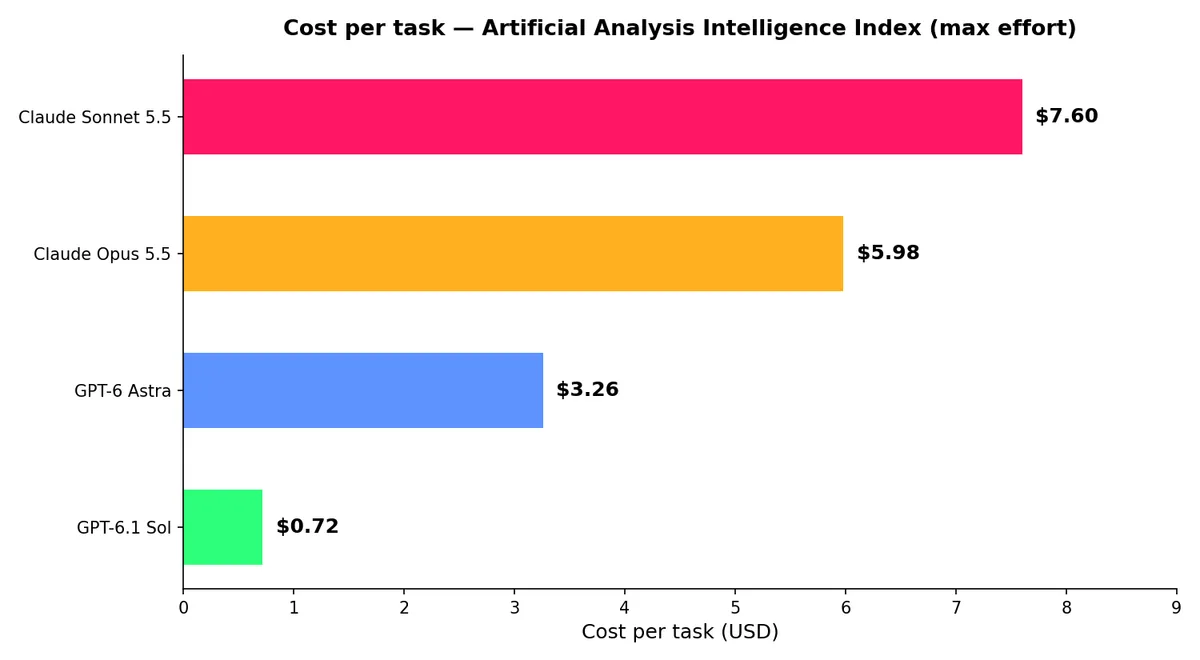
OpenAI's GPT-6.1 Sol arrived at DevDay 2026 with benchmarks that look almost unfair: near GPT-6 Astra intelligence at one-fifth of the price, $0.72 per task against $5.98 for Claude Opus 5.5. But benchmarks are marketing until someone builds real things with the model. YouTuber Chase AI did exactly that, putting Sol 6.1 and Claude Sonnet 5.5 through four genuine build jobs: JavaScript motion graphics, a boutique-hotel landing page, a 3D travel dashboard, and a full browser game. The results tell a very different story from the leaderboard.

If you want the pure benchmark breakdown first, read our GPT-6.1 Sol vs Claude Sonnet 5.5 benchmark comparison. This post is about what happens when both models do actual work.
The price illusion: same sticker, 10x cost gap
Both models list at $2 per million input tokens and $10 per million output tokens. On paper, a tie. In practice, Artificial Analysis measured cost per index task at maximum effort and the gap is enormous: GPT-6.1 Sol costs $0.72 per task, Claude Sonnet 5.5 costs $7.60. That is more than a 10x difference at the identical list price.
Why? Token efficiency. Sonnet 5.5 burned roughly 193,000 tokens per task in Artificial Analysis testing, about seven times GPT-6 Astra's total, while Sol sips tokens to reach a similar score. OpenAI's cached input pricing at $0.10 per million (95% off standard input) pushes the gap even wider for agentic workloads that resend long system prompts and tool lists on every turn.
Four real builds: what actually happened
Chase ran both models in their native coding environments (Sol in Codex, Sonnet in Claude Code) on the same four jobs. Here is the scorecard:
| # | Test | Winner | Token use |
|---|---|---|---|
| 1 | JavaScript motion graphics | Sonnet 5.5, clearly | Sol ~70k, Sonnet ~300k |
| 2 | Boutique-hotel landing page | Tie | Sol 109k, Sonnet ~200k |
| 3 | 3D travel dashboard | Sonnet 5.5, clearly | Sol ~150k, Sonnet ~400k |
| 4 | World of Tanks browser game | Even | Sol ~350k, Sonnet ~700k |
Test 1, motion graphics: Sonnet won outright. Its animation had better physics, timing, and polish. Sol used less than a quarter of the tokens and it showed.
Test 2, landing page: a genuine tie, split down the middle. Sol produced the better-looking page; Sonnet shipped a working availability checker. Design went to Sol, functionality went to Sonnet.
Test 3, 3D dashboard: Sonnet's clearest win. Better visuals, richer interaction, more convincing city details, fares, weather, and imagery. Sol's version felt flat by comparison despite using fewer than half the tokens.
Test 4, the game: the most subjective round. Sol built the better-looking tank; Sonnet built the better map and the tank felt better to drive. But the clock told its own story: Sol took over two hours, Sonnet about one. Sol is cheaper per task but slower in wall-clock time, a trade-off that matters when a developer is waiting.
The benchmark scoreboard, for reference
The independent Artificial Analysis head-to-head across 11 evaluations: Sonnet 5.5 won 7, GPT-6.1 Sol won 4. Sonnet's biggest margins came on AA-Briefcase (66% vs 53%), GDPval-AA (67% vs 54%), AutomationBench-AA (71.3% vs 66.6%), and Terminal-Bench 4.0 (63.6% vs 56.1%). Sol's wins clustered on document work and accuracy: GDP.pdf (32.0% vs 25.8%), AA-Omniscience accuracy (62.0% vs 53.95%), and long-context AA-LCR (83.0% vs 82.7%). Composite Intelligence Index: Sonnet 56, Sol 52.
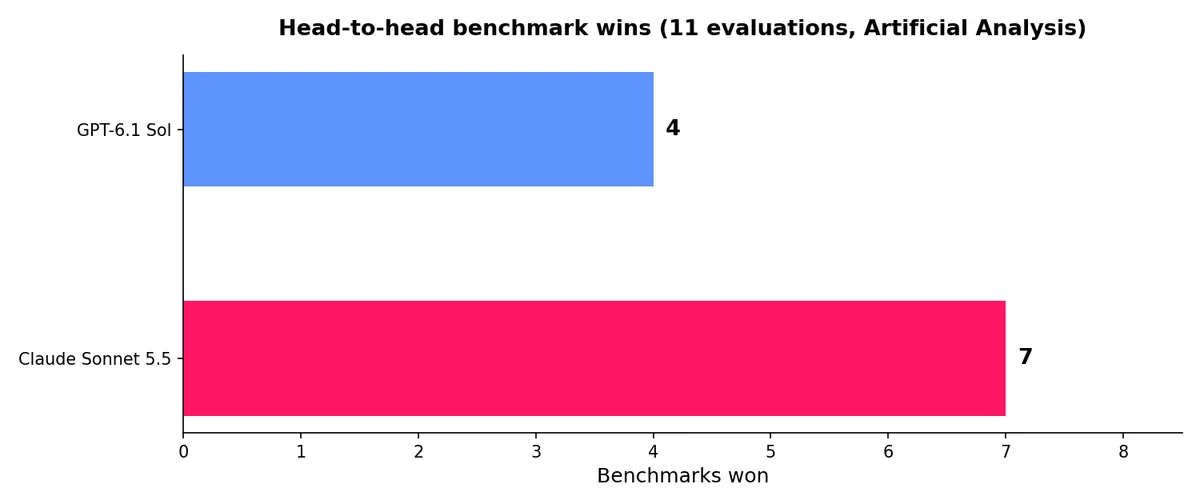
So the benchmarks and the real builds agree on the direction: Sonnet 5.5 is the stronger model, Sol 6.1 is the cheaper one. What the benchmarks hide is how much cheaper, and how the quality gap feels in practice. It is small enough that on two of four real jobs, Sol tied or matched Sonnet.
What this means for your team
Pick Claude Sonnet 5.5 when the quality of the artifact matters most and a human reviews the output: client-facing design, complex frontend work, polished deliverables. Budget for the token burn, roughly 10x the per-task cost at maximum effort.
Pick GPT-6.1 Sol for high-volume agentic workloads: background agents, long-running automation, cost-sensitive pipelines. You get roughly 90% of the quality at roughly 10% of the per-task cost. Just expect slower wall-clock time on interactive builds.
Watch the effort dial. At lower effort settings the cost gap narrows considerably; at maximum effort Sonnet 5.5 can cost more per task than even Opus 5.5. Match the effort level to the stakes of the task, not the other way around.
The honest summary, and the video's verdict: Sol 6.1 sits slightly below Sonnet 5.5 in quality, far ahead in token efficiency, and behind on speed. Raw benchmark scores alone will not tell you any of that.
At CodeMyPixel we build AI agents that automate repeated business work, and model selection is where those projects win or lose their margins. If your team is burning budget on the wrong model tier, talk to us.
Is GPT-6.1 Sol really cheaper than Claude Sonnet 5.5?
Yes, dramatically, despite the identical $2/$10 list price. Artificial Analysis measured $0.72 per task for Sol 6.1 versus $7.60 for Sonnet 5.5 at maximum effort. Sol reaches similar benchmark scores using far fewer tokens, and its $0.10 cached input pricing widens the gap further on agentic workloads.
Which model won the real-world tests?
Claude Sonnet 5.5 won two of the four builds outright (JavaScript motion graphics and the 3D travel dashboard), tied on the landing page, and drew even on the browser game. Sol 6.1 never won a round outright but matched Sonnet twice while using roughly half the tokens.
Should benchmarks decide which model my team uses?
No. Benchmarks measure capability per task, not cost per task or wall-clock time. In these tests the model with the lower benchmark score was 10x cheaper per task and tied half the real builds. Evaluate on your own tasks, at your own effort settings, and price the token burn.
Where can I use GPT-6.1 Sol right now?
GPT-6.1 Sol (API id gpt-6.1-sol) is available in ChatGPT Work and Codex for Plus, Pro, Business, Enterprise, and Edu users, plus the API. It is not yet in regular ChatGPT chat or on the Free and Go plans. A faster Ultrafast tier is expected soon.
- GPT-6.1 Sol
- Claude Sonnet 5.5
- AI models
- benchmarks
- cost per task