AI7 min readBy JH Akash
Mistral Voxtral 3 Explained: Voice Agent Stack vs ElevenLabs Realtime
Mistral shipped Voxtral 3 on Oct 20, 2026: 50+ languages of transcription, a real-time voice agent SDK on LiveKit, and TTS from $13 per million characters. The same day, ElevenLabs released Eleven Realtime, two speech-to-speech models with 0.57s response time. Full breakdown inside.
Mistral Voxtral 3 Explained: Full Voice Agent Stack vs ElevenLabs Realtime
Voice AI had a busy Tuesday. On October 20, 2026, Mistral shipped Voxtral 3, a full voice agent stack with three transcription tiers, a text-to-speech model, and a real-time voice agent SDK. The very same afternoon, ElevenLabs released Eleven Realtime, two speech-to-speech models built for live AI conversation.
Two labs, two very different architectures, one goal: AI that can hold a real phone call. Here is what each one does, what each costs, and how to pick between them.
Quick verdict
| Mistral Voxtral 3 | ElevenLabs Eleven Realtime | |
|---|---|---|
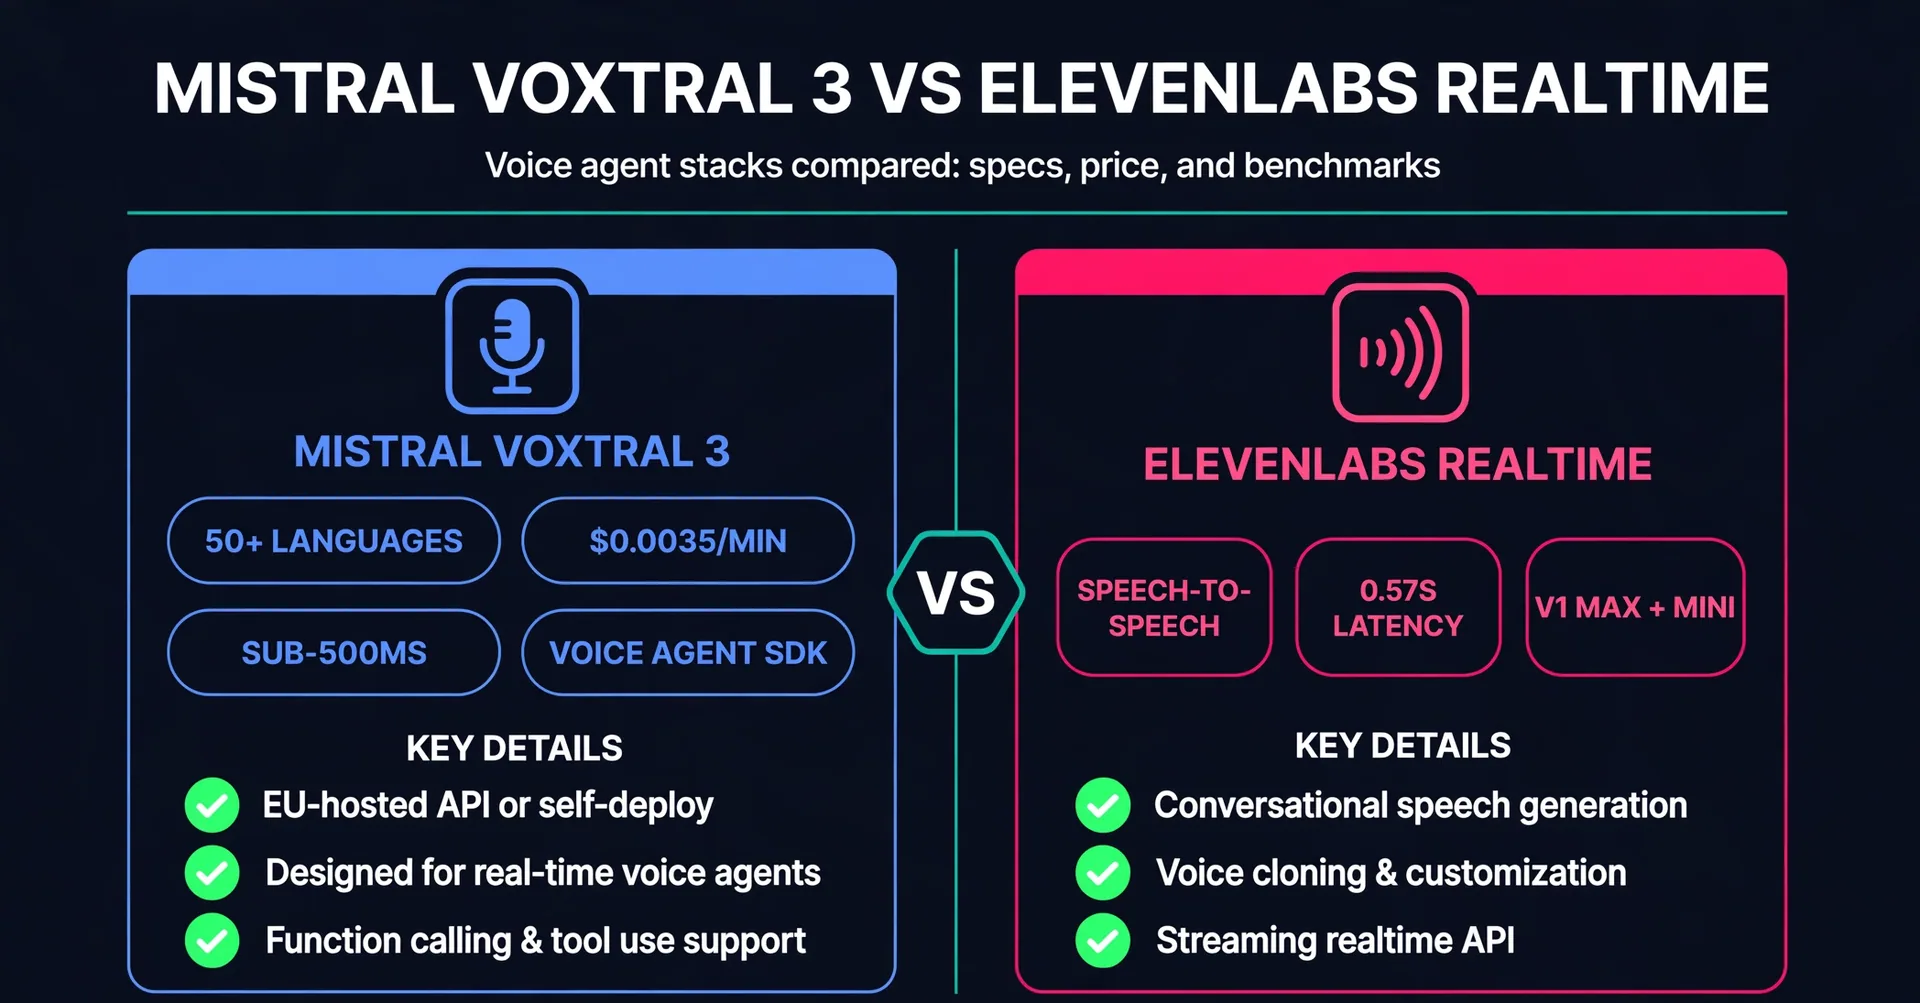
| Architecture | Modular: STT + LLM + TTS pipeline with SDK | End-to-end speech-to-speech |
| Transcription languages | 50+ languages | Not separately specified |
| TTS languages | 35+ languages, 50+ dialects | 90+ languages (Eleven v4 family) |
| Turn latency | Under 1 second per turn, sub-500ms realtime transcription | About 0.57s response (v1 Max) |
| Transcription price | From $0.0035/min | Not published as a flat rate |
| TTS price | $13 per 1M characters | From $40/M characters (Flash/Turbo, Oct 2026 pricing) |
| Voice cloning | From 30+ minutes of audio (Pro Voice) | Instant clone from 10 seconds (Eleven v4) |
| Deployment | EU-hosted API or self-hosted | ElevenLabs cloud, OpenAI-compatible API |
| Best for | Regulated industries, multilingual transcription, budget voice agents | Naturalness-first voice agents and support bots |
Bottom line: pick Voxtral 3 when data residency, multilingual coverage, or per-minute cost drives the decision. Pick Eleven Realtime when the voice itself has to sound flawless. Read on for the full numbers.
What Mistral Voxtral 3 actually includes
Voxtral 3 is not one model. It is a family of speech models plus a voice agent SDK that stitches them together. Every part is available today through Mistral's API, hosted in the EU, or deployed on your own infrastructure.
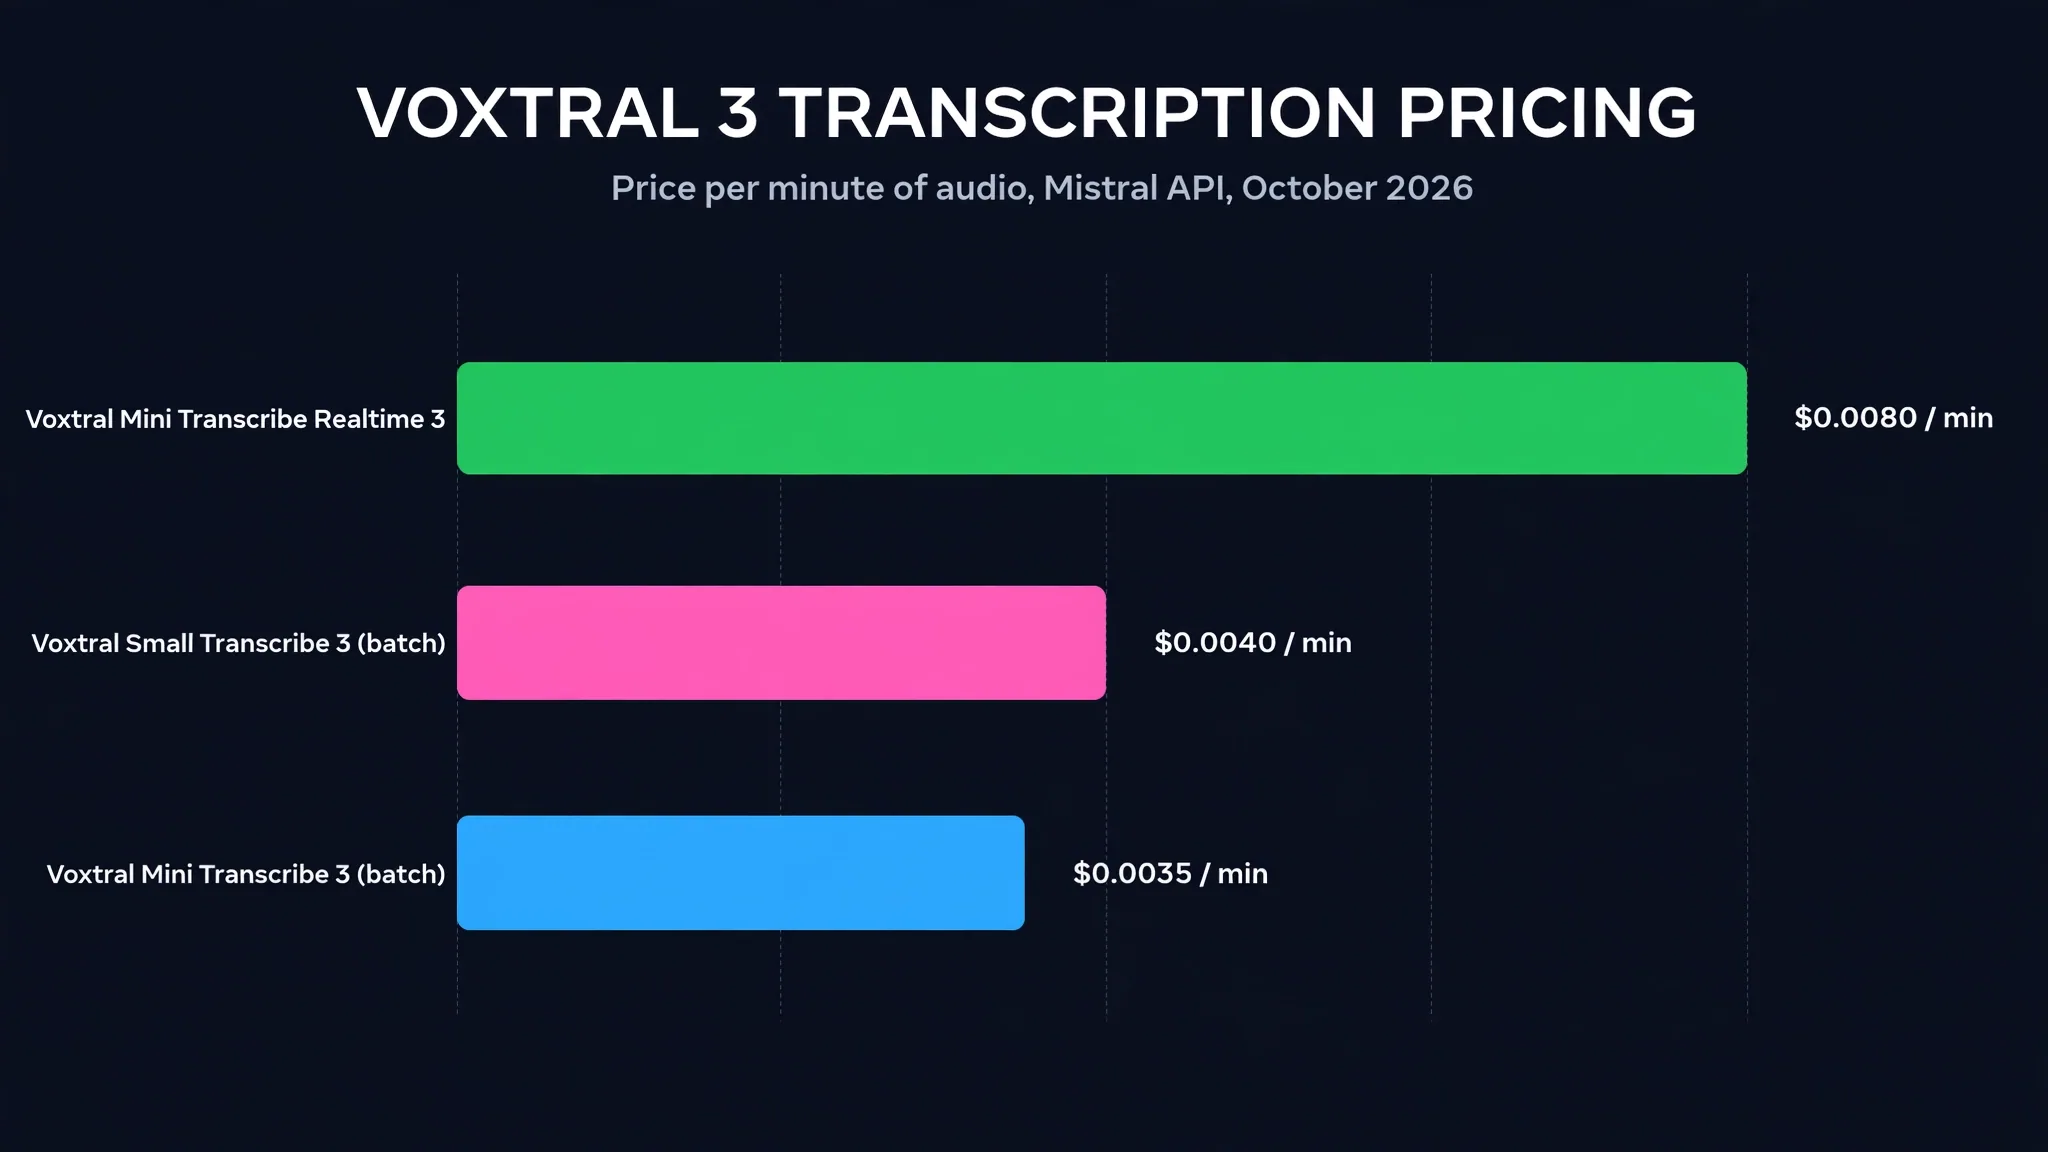
Voxtral Mini Transcribe 3: $0.0035 per minute
The budget transcription tier. A 4-billion-parameter speech-to-text model built for batch workloads, priced at $0.0035 per minute of audio. Both batch models accept key terms and extra context text, so domain vocabulary gets recognized without fine-tuning.
Voxtral Small Transcribe 3: $0.004 per minute
The flagship transcription model: 50+ languages including all 24 official EU languages, plus Asian and Indic languages with fewer resources. It adds speaker diarization, end-of-turn detection (it knows when the caller stopped talking), and context biasing for specialized terms. Mistral says it beats Whisper, Scribe v2, and Gemini 3.5 Transcribe on their own multilingual tests. More on those numbers below.
Voxtral Mini Transcribe Realtime 3: $0.008 per minute
The agent-focused tier: 35+ languages with transcription latency below 500 milliseconds, including speaker identification and vocabulary use. This is the model that feeds the voice agent SDK.
Voxtral Speech 3: $13 per 1 million characters
The text-to-speech model covers 35+ languages and 50+ dialects, with emotion, pacing, and emphasis controllable as instruction variables. Voice presets ship in 18 languages, from Arabic and Hindi to Vietnamese. Voice cloning needs 30 or more minutes of audio, and a Pro Voice option adapts a speaker's character and emotional range across languages from about 30 minutes of recordings. Same $13 price for batch and realtime use through one API. Mistral positions it as cheaper than OpenAI TTS-1, Deepgram, ElevenLabs Flash, and Gemini Flash.
The voice agent SDK: LiveKit, under one second per turn
The headline piece is the SDK, built on LiveKit. Voxtral Mini Transcribe Realtime 3 listens, a general model like Mistral Small reasons and calls tools, and Voxtral Speech 3 answers in the tone of the conversation. No stage waits for the one before it, so Mistral says each turn completes in under one second and the agent stops talking when the caller cuts in.
During a call the agent can verify a caller's identity, check a bill, or book an appointment, using function calling, web search, and retrieval over your own systems. It answers and places calls over SIP, runs in browsers and apps over WebRTC, and plugs into telephony, IVR, and contact-center software. Each stage is a separate model, so you can swap the LLM, the voice, or the language without rewriting the agent.
Deployment is the sovereignty pitch: run the stack on Mistral's EU API or on your own infrastructure, with control over where conversations are processed and whether audio is retained. Note that the announcement does not link downloadable open weights; self-hosting is offered through Mistral's own deployment channel.
What ElevenLabs shipped: Eleven Realtime v1 Max and v1 Mini
ElevenLabs went end-to-end instead of modular. Two speech-to-speech models, released the same day:
- Eleven Realtime v1 Max: the accuracy play. ElevenLabs reports 98.8% on the Big Bench Audio benchmark with about 0.57 seconds of response time, and says no model on the Artificial Analysis speech-to-speech leaderboard is both faster and more accurate right now. Aimed at demanding tasks like customer-support bots.
- Eleven Realtime v1 Mini: the cost play for natural, everyday conversations. It can tell when a speaker has finished versus just saying "mm-hmm", which matters a lot for natural turn-taking.
Both run through the ElevenAgents platform and an OpenAI-compatible Realtime API, so existing OpenAI voice-agent code can point at ElevenLabs endpoints. Pricing is per minute of audio plus token usage, with Max priced above Mini; ElevenLabs has not published a flat per-minute number the way Mistral has. Independent benchmarks beyond the company's own claims have not been published yet.
Benchmarks: who transcribes better
Mistral published word error rate numbers on the FLEURS benchmark across 45 languages, with inferred language. Voxtral Small Transcribe 3 posts 4.0%, tying Microsoft AI Transcribe 2 in Mistral's own numbers, ahead of Gemini 3.5 Transcribe at 4.5%, Scribe v2 at 4.9%, GPT Transcribe at 5.6%, and Whisper large-v3 at 14.9%.
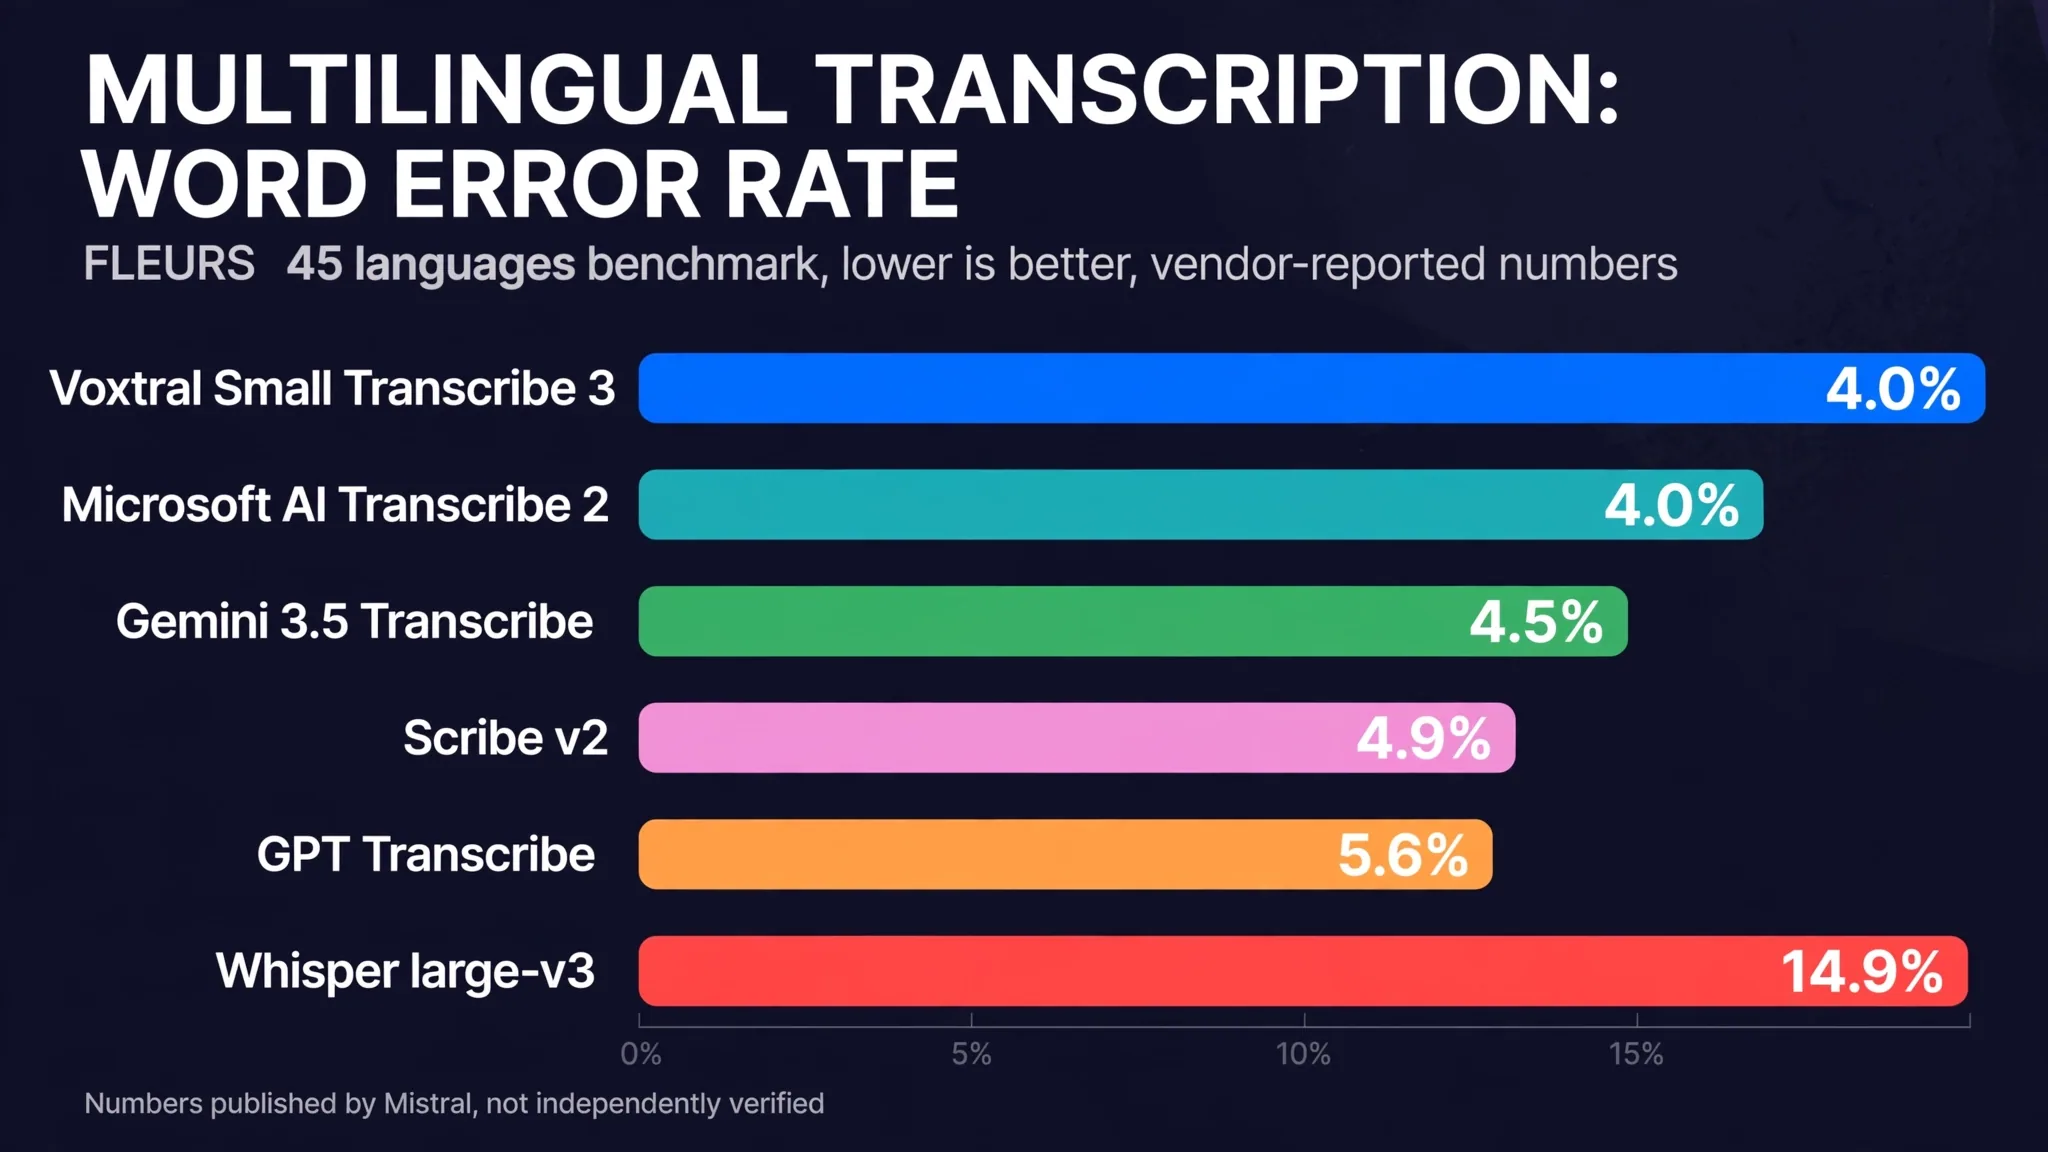
Two important caveats. First, these are vendor-reported numbers from Mistral's launch post, not independently verified, and the post publishes no per-language breakouts or customer names. Second, do not compare this chart to ElevenLabs' Big Bench Audio 98.8% figure: different benchmarks measure different things, and cross-benchmark winners are not declared here for that reason.
For Eleven Realtime, the honest statement is that ElevenLabs' own Big Bench Audio and Artificial Analysis claims are the only numbers available right now. Treat both vendors' numbers as marketing until third parties reproduce them.
Which one should you build on?
Choose Voxtral 3 if:
- You need EU data residency or a self-hosted stack your compliance team can audit.
- Transcription is the workload: 50+ languages at $0.0035 to $0.004 per minute is genuinely cheap.
- You want a modular pipeline where the LLM, the voice, and the language can be swapped independently.
- You need tool use mid-call: booking, invoice lookups, identity verification over SIP and WebRTC.
Choose Eleven Realtime if:
- The voice itself is the product: premium naturalness, character voices, branded agents.
- You want end-to-end speech-to-speech without wiring STT and TTS together yourself.
- You already build on ElevenAgents or want an OpenAI-compatible Realtime API.
- You need 10-second instant voice clones rather than 30-minute voice adaptation.
Consider both if: you are building voice agents for clients and pricing is per-project. Voxtral's $0.0035/min batch transcription and $13/M-character TTS set a low floor for high-volume work, while ElevenLabs' 10-second cloning and speech-to-speech naturalness can justify a premium where the voice is the differentiator. CodeMyPixel builds exactly this kind of evaluation into every AI agent development engagement: test both stacks against your real calls before committing.
FAQ
How much does Voxtral 3 cost?
Transcription costs $0.0035 per minute for Voxtral Mini Transcribe 3 in batch, $0.0040 for Voxtral Small Transcribe 3, and $0.008 for Voxtral Mini Transcribe Realtime 3. Voxtral Speech 3 text-to-speech costs $13 per million characters, the same price for batch and realtime use.
Is Voxtral 3 open source?
The launch announcement does not link open weights or a downloadable license. Mistral offers the models through its API with EU, US, and global endpoints, and teams that need audio to stay in their own environment can ask Mistral about self-hosted or private-cloud deployment.
How accurate is Voxtral Small Transcribe 3?
On Mistral's FLEURS test across 45 languages, it posts a 4.0% word error rate with inferred language, against 4.5% for Gemini 3.5 Transcribe, 4.9% for Scribe v2, 5.6% for GPT Transcribe, and 14.9% for Whisper large-v3. Microsoft AI Transcribe 2 ties it at 4.0%. These are Mistral's published numbers, not independently verified.
What is the difference between Voxtral 3 and ElevenLabs Eleven Realtime?
Voxtral 3 is a modular stack: separate speech-to-text, LLM, and text-to-speech models joined by a LiveKit-based SDK. Eleven Realtime is end-to-end speech-to-speech: one model takes audio in and produces audio out, in two tiers (v1 Max for accuracy, v1 Mini for cost).
Can Voxtral Speech 3 clone a voice?
Yes, from 30 or more minutes of audio. A Pro Voice option adapts a speaker's character, emotional range, and style across languages from about 30 minutes of recordings. Voice presets are available in 18 languages.
When was Voxtral 3 released?
Mistral announced Voxtral 3 on October 20, 2026, one day after its Timestral time-series model. ElevenLabs released Eleven Realtime the same afternoon.
Which is better for a customer support voice agent?
If support calls run in many languages and budgets are tight, Voxtral 3's $0.004/min transcription with speaker diarization and its LiveKit SDK are the practical pick. If callers must never feel they are talking to a robot, Eleven Realtime v1 Max's 0.57-second, speech-to-speech pipeline is built for that. Most teams should pilot both on real call recordings before choosing.
Where can I get a voice agent built for my business?
CodeMyPixel designs and builds custom AI agents that handle calls, bookings, and follow-ups for real businesses, including voice agents on stacks like Voxtral 3. Start with a free AI Opportunity Review to see which parts of your operation a voice agent can take over.
Sources: Mistral AI launch post (mistral.ai/news/voxtral-3), Technobezz, The Decoder, The Circuitry, ai-tldr, explainx.ai. All benchmark and pricing figures are as reported by the vendors on October 20, 2026, and were not independently verified.
- mistral voxtral 3
- voice ai
- voice agents
- elevenlabs
- text to speech
- speech to text